Data Submission Introduction
This page reviews the background information needed to submit data, and an overview of the steps to complete the process.
The major steps in the data submission process are as follows:
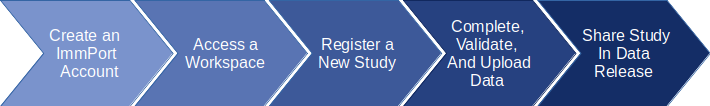
For details on each data submission step, please see: Getting Started: Workspaces and Studies
Data Submission is a step in the overall process of data curation and sharing in ImmPort. The goal of submitting data through ImmPort is to publicly share the data and help advance scientific discovery in the immunology research community.
For additional questions on Data Submission, please contact the ImmPort team: ImmPort_Helpdesk@immport.org
What is an ImmPort Study?
A study is a collection of data generated based on a research or clinical study protocol. A study may be focused on data referenced in a manuscript and should be sufficient for the data consumer to fully understand the conclusions presented in the manuscript and conduct a reanalysis.
What Type of Data is in ImmPort?
ImmPort currently hosts studies across various immunology-related research focuses and assay methods. For a breakdown of the types of studies currently shared in ImmPort, please explore our Shared Data site: ImmPort Shared Data
How is ImmPort Data Stored?
ImmPort metadata and data is shared in a relational database model. Our current data model can be viewed here: Data Model
The model depicts mulitple related tables which capture metadata and data on an ImmPort study. Many tables also incorporate terms from clinical and research ontologies. The information in these tables is captured in ImmmPort Submission Templates, which are downloaded as Excel or tablular(.txt) files, completed by the user, and then uploaded to ImmPort. ImmPort also supports uploading non-ImmPort template files to provide additional data. Therefore, to provide information for a study, a user typically uploads several completed submission templates and non-template files based on their type of study.
Templates and descriptions of the templates are available for download here: Template Catalog
What Format of Metadata and Data is Uploaded?
Study metadata is captured as row-based entries using the ImmPort Excel templates. The templates may also be completed as tabular (.txt) files, however the user-friendly excel templates are recommended for new users. The Basic Study Design Template is also available to be completed in an online form-based interface.
Results data for ELISA, ELISPOT, HAI, Neutralizing Antibody Titer, RT-PCR, Flow Cytometry, HLA, KIR, Gene Expression, RNA Sequencing, Genotyping, MBAA, and non-sample based assessments are recommended to be uploaded using ImmPort templates, but may also be uploaded as non-ImmPort template files. Other study types, including Mass Spectrometry and Image Histology, require a non-ImmPort template results file to be uploaded. ImmPort supports uploading common file types such as .pdf, .doc(x), .xls(x), .txt, as well as scientific file types such as .fcs files. For additional questions on supported file types please contact the ImmPort team: ImmPort_Helpdesk@immport.org
If your study’s data is currently shared in another repository, you can still create a study in ImmPort without duplicating the data from the other repository. ImmPort allows you to upload metadata in the ImmPort format and then link the results data from the other repository via a URL field in the ImmPort templates.
How much data should be uploaded to ImmPort?
The data and metadata shared should align with the NIH’s FAIR policy for making data Findable, Accessible, Interoperable, and Reusable (NIH FAIR Data Sharing Policy). Overall, the contents of the data and metadata shared should be sufficient to fully understand the results of the linked publication.
Task-Oriented Reference Guide
What this section is
The pages below are a supplementary, task-oriented layer on top of this introduction and the official Template Documentation. Where a detail here seems to conflict with a template's own reference page, the template page (and ultimately the submission template/validator) wins.
The material above answers "what are the constraints on field X?" one template at a time. It's much harder to answer task-shaped questions like "what's the full sequence of templates I need to upload a CyTOF experiment?" or "why did my upload get rejected?" — that knowledge exists, but it's scattered across PDFs, Excel troubleshooting sheets, and the underlying validation engine's source code. The pages below pull it together in one place so that anyone preparing an ImmPort submission — whether filling out templates by hand or scripting the upload — can use it directly:
| Section | What's there |
|---|---|
| Getting Started | Create a workspace, register a study, and choose between the two upload paths (SRW vs. templates). |
| Templates | The full template catalog and the correct upload order for a typical study. |
| Example Upload Packages | Ready-made example packages to use as fixtures. |
| Validation | Plain-English explanations of every recurring validation rule type, plus a common-errors FAQ. |
| Data Standards and Compliance | Published data standards (HIPC, CDEs), the controlled-vocabulary/ontology mechanism, and Subject De-Identification requirements. |
| Workflows | Task-oriented guides — including per-assay upload sequences transcribed from the official flow-diagram PDFs. |
| API Reference | The REST endpoints an automated client needs to upload and validate a package end-to-end. |
How to use this guide
- Start at Getting Started if you don't yet have a workspace or registered study.
- Use the Template Catalog + Upload Order to figure out which templates you need and in what order/bundle — or start from an example package if you need a concrete fixture.
- Check Workflows for your specific assay type or task — these encode constraints (like "upload these N templates in the same package") that aren't repeated on the individual template reference pages.
- Before assuming a validation behavior, check the Validation Rule Glossary and the common-errors FAQ — generic field descriptions can be less precise than the actual enforced rule.
- Respect de-identification requirements and check field values against the relevant controlled vocabulary before submitting.
- If you're scripting the submission, use the API Reference to drive the upload → validate → status → report loop.
Provenance matters
Wherever a page in this section states a hard rule (required/optional, bundling constraints, error conditions), it links back to its source — a flow-diagram PDF, a template page, or the validator — so you can verify it yourself rather than taking the paraphrase on faith.